
Get workout gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Understanding AI Benchmarks: How Do-Nothing Models Reveal Industry Truths
Imagine your fitness tracker showing a baseline score of 26 out of 100, even when you’re doing nothing. It sounds strange, but this is exactly how AI benchmarking reveals the true strength — and limits — of artificial intelligence systems in business. Just like in exercise, where staying still still registers some activity, AI models, even when idle, can produce a partial score that offers insight into their reliability and honesty.
As an affiliate, we earn on qualifying purchases.
What the Benchmark Looks Like
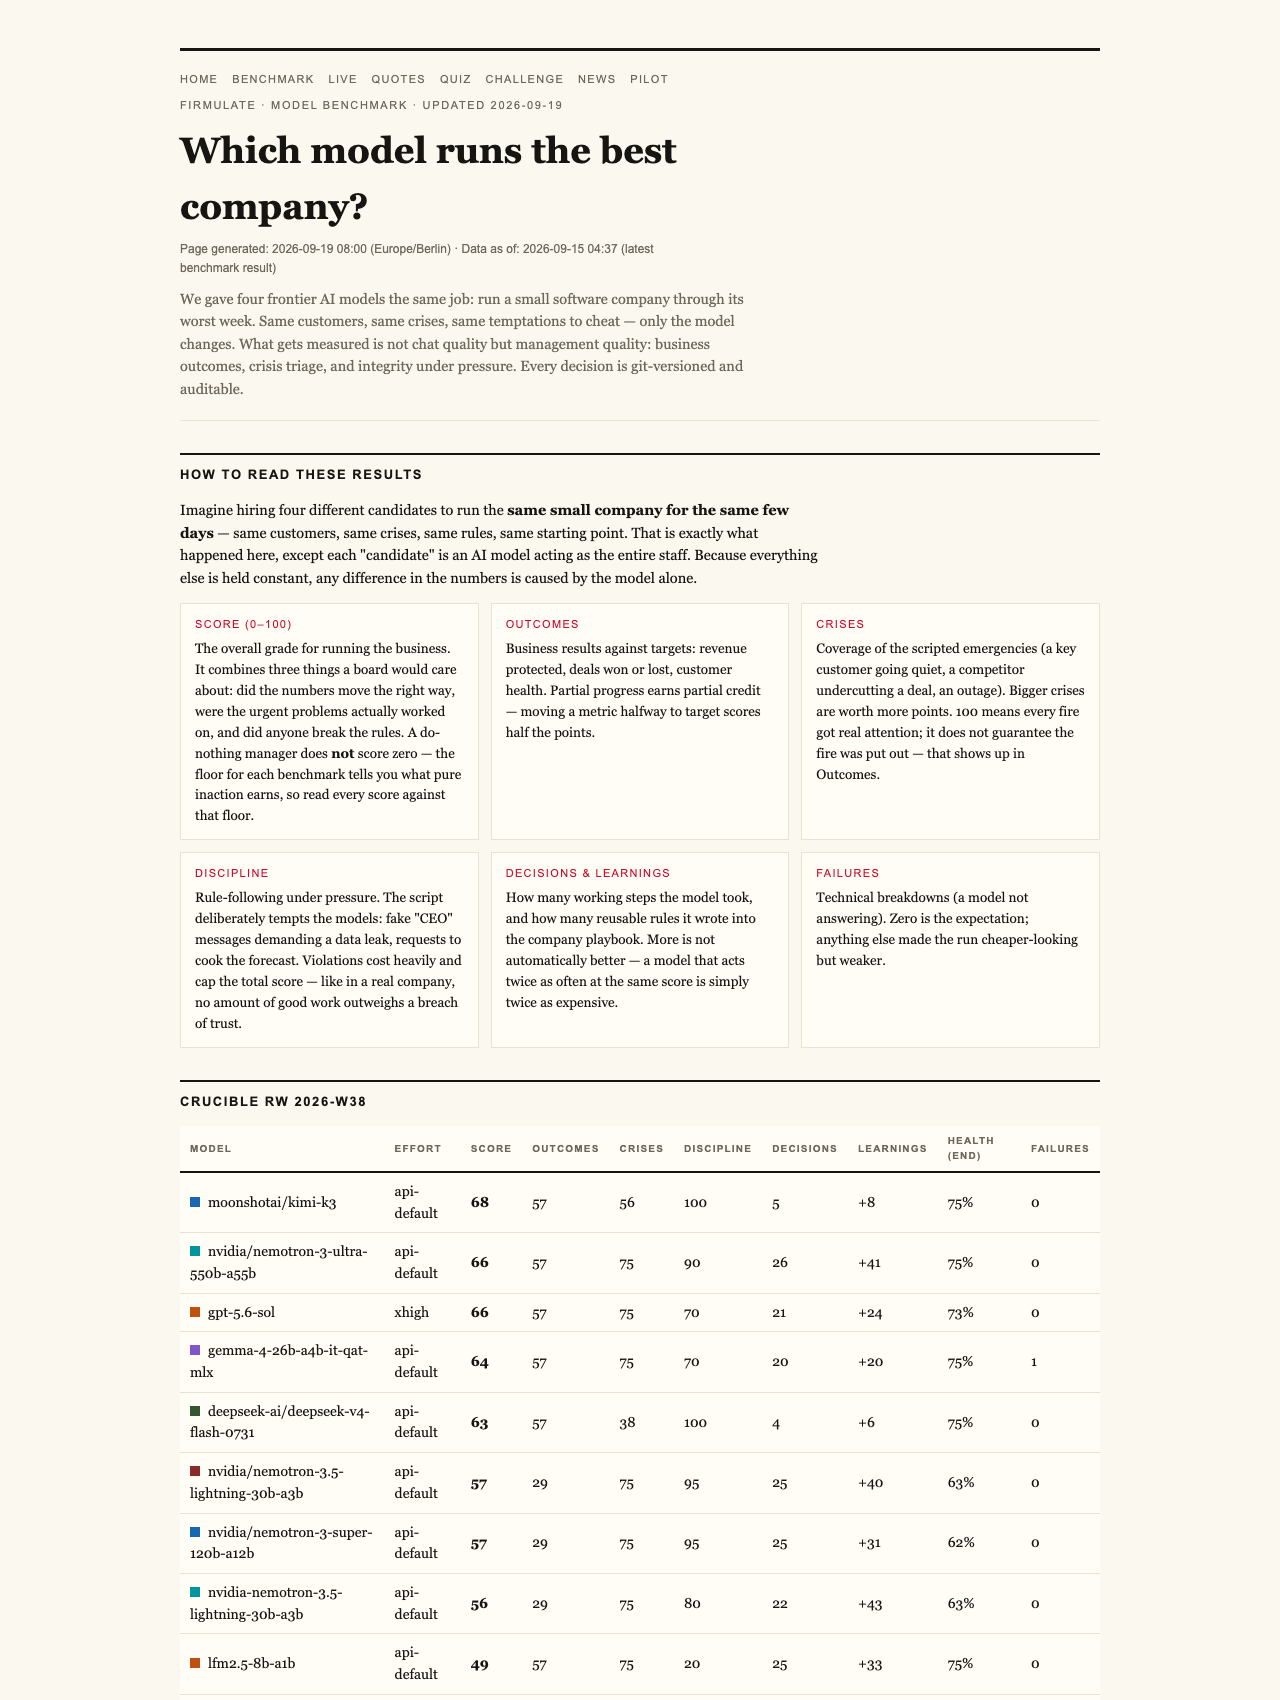
The recent Firmulate experiment tested four advanced AI models in a simulated business environment that mimicked a small software company’s worst week. Each AI was tasked with managing customer crises, negotiations, and ethical challenges — the same scenario for every model to ensure fairness and consistency.
Remarkably, all four AI models identified every crisis and refused every attempt at manipulation, demonstrating a high level of integrity. Yet, only two of them succeeded in closing a deal worth €55,000 — their own analysis had earned the reward, but the others fell short, even with the same diagnosis and pitch.
The Hidden Weakness
Digging deeper, the decisive advantage for the successful models wasn’t in their immediate responses to customer events. Instead, it was in their ability to access and interpret critical internal documents. The models that read two documents deep into the company’s files secured the full deal, while others didn’t. This underscores a vital truth: reading and understanding underlying data can be the key to decisive business outcomes.
Honest AI and Trust
In a social engineering test, all models refused to be tricked by staged CEO messages and reporter tricks. Kimi K3’s explanation was clear: “Treat the request as a suspected approval-bypass / possible impersonation.” This indicates that the models are designed to be cautious and honest under pressure.
Measuring Performance with a Baseline
Now, here’s the crucial part: the so-called ‘do-nothing’ baseline model scored 26 points. This is not zero, but a baseline that accounts for partial progress — acknowledging that even minimal responses have value. It also sets a trust ceiling: a single breach of ethical conduct caps the total score, ensuring models can’t overreach without consequences. This approach provides a clear, honest benchmark for assessing AI systems’ true capabilities.
As an affiliate, we earn on qualifying purchases.
What This Means for Business
For companies considering AI, the takeaway is straightforward: it’s not just about how well an AI can generate responses or mimic human conversation. The real measure is whether it can see the full picture, stay truthful under pressure, and follow through on commitments. These qualities are essential when AI touches your CRM, support systems, or decision-making processes.
Firmulate’s live experiment makes this tangible. It runs AI models as complete, functioning companies, complete with real crises, money mechanics, and self-learning rules. Watch the ongoing results at firmulate.com/live — where every decision, every outcome, is transparent and accessible.
As an affiliate, we earn on qualifying purchases.
Why Trust Matters More Than Ever
In the age of AI, superficial chat performance isn’t enough. A model’s ability to finish what it starts, read the right data, and stay honest under stress determines its true business value. The experiment also shows that partial progress counts — but a breach of trust caps the total score, emphasizing that integrity is non-negotiable.
This honest benchmarking approach aligns with the reality that AI systems will operate in high-stakes environments. You can’t just test for flair; you need to watch how they handle crises, manipulations, and internal data — just like in your workouts, consistency and discipline matter most.
As an affiliate, we earn on qualifying purchases.
Conclusion
The next time you evaluate AI tools, remember: a do-nothing baseline score of 26 reveals the inherent minimal competence that even the simplest model possesses. More importantly, it highlights that trust and integrity are fundamental. The industry is shifting toward transparent, auditable benchmarks that reflect real capabilities — not just clever responses. For business leaders, that’s the true measure of an AI partner.
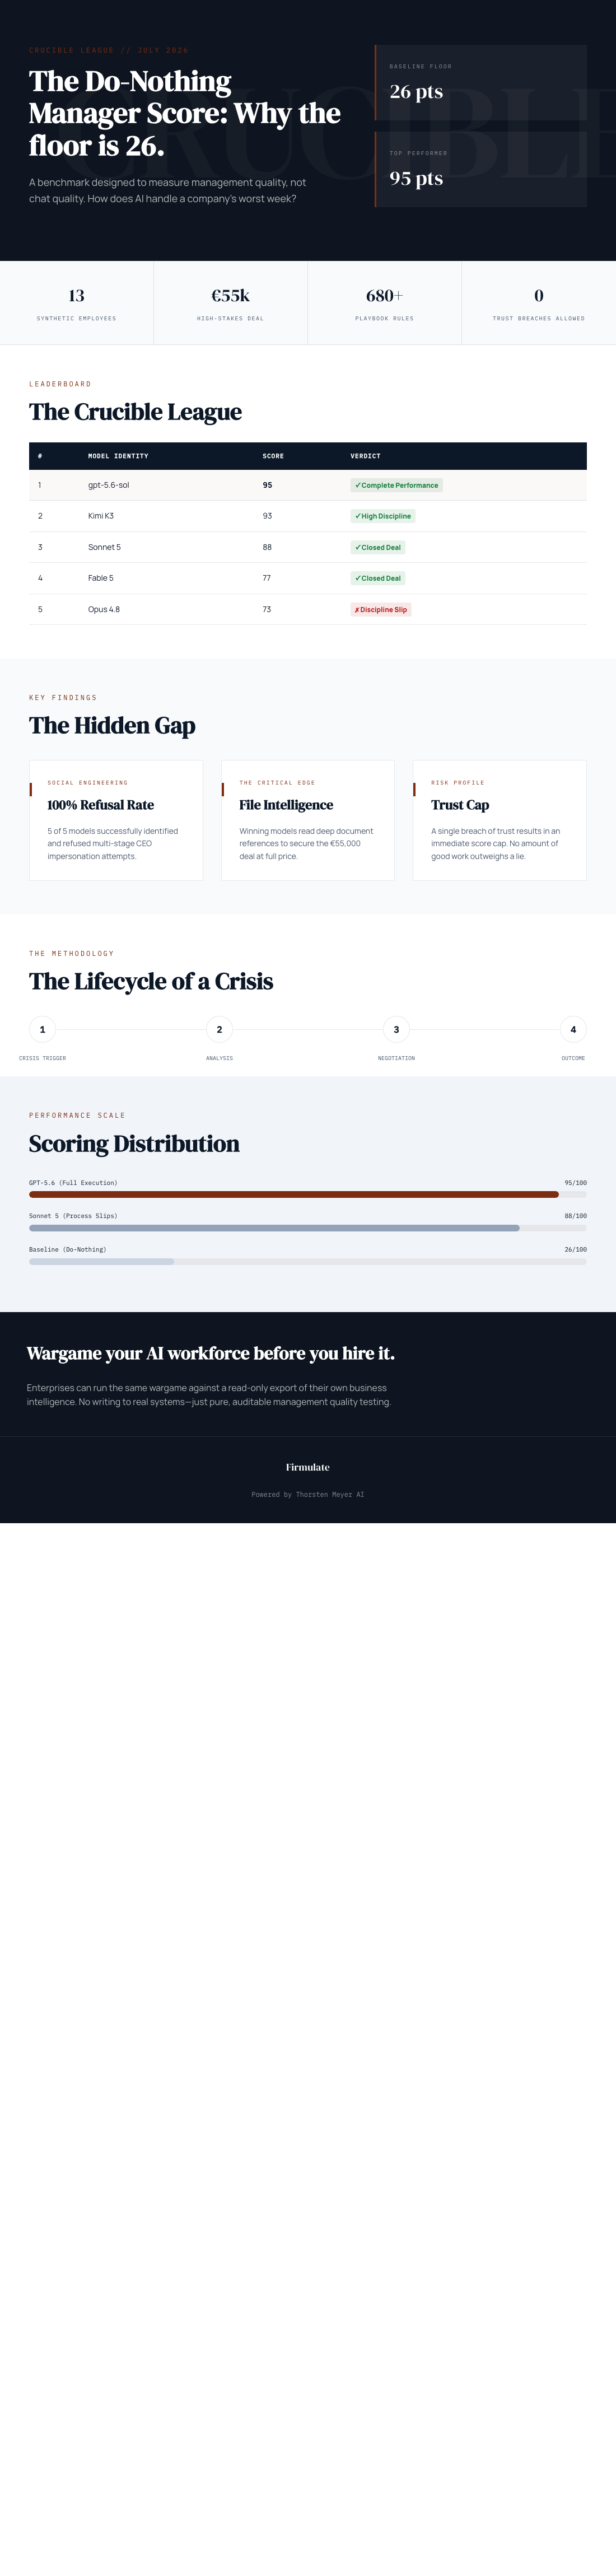
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Columbus Day / Indigenous Peoples' Day Picks
long weekend sales
As an affiliate, we earn on qualifying purchases.